
Robohub.org
Interactive world simulator for robot policy training and evaluation
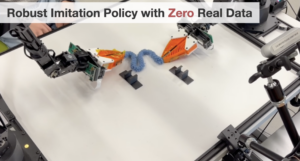
Imagine you want to teach a robot to push an object on a table. The standard recipe in robot learning is to collect hundreds of expert demonstrations on a real robot, train an imitation learning policy on that data, and then evaluate the policy by running it many times on the same real robot. Both stages (data collection and evaluation) are slow, expensive, and hard to reproduce: hardware breaks, lighting changes, objects drift out of place, and every new task means more hours in the lab.
A natural question is whether we can replace some of this real-robot work with a simulator. Classical physics-based simulators are powerful, but building one for a new task means manually modeling geometries, contacts, friction, and deformation, and the resulting simulator often still does not match reality closely enough for policies trained inside it to transfer.
In our work, we take a different route. We build an Interactive World Simulator: a learned, action-conditioned video prediction model that, given the current image and a sequence of robot actions, predicts the next frames purely in pixel space, with no physics engine inside. You can plug in a teleoperation device and control the robot through this learned world model for more than 10 minutes at 15 FPS on a single RTX 4090, and the predicted video stays stable and physically plausible.
The key idea is that, if the simulator is faithful enough, we could unlock two long-standing bottlenecks in robot learning:
– Data generation for training becomes cheap, because we can collect demonstrations inside the simulator.
– Policy evaluation becomes scalable and reproducible, because we can roll many policies through the simulator under identical conditions.
What the world simulator can do
We trained our world simulator on four manipulation tasks that span very different physical regimes: T pushing (rigid-body contact), rope routing (deformable–rigid interaction with a clip), mug grasping (fine-grained gripper dynamics), and pile sweeping (manipulating piles of objects). All four behaviors are learned from interaction data alone, with no physics priors hard-coded.
A few examples of what the model captures:
Rope routing: it correctly distinguishes between the rope actually being inserted into the clip and the rope swinging past it without making contact. Crucially, it does not bias toward either outcome — it follows what the actions imply.
Mug grasping: it captures fine-grained effects such as the mug slipping out of the gripper, or the handle being nudged and rotated.
Pile sweeping: it can generate video for multiple viewpoints consistently
You can try this directly on our project page: just open a browser and play with it using your keyboard!
How we built the interactive world simulator
At a high level, Interactive World Simulator is trained in two stages. First, we trained an autoencoder that compresses RGB images into compact 2D latent representations and reconstructs them back into images. This lets the model reason in a lower-dimensional space while still producing high-fidelity pixel-level outputs.
Second, we froze this autoencoder and trained an action-conditioned dynamics model in the latent space. Given past visual latents and robot actions, the model predicts the next latent state, which is then decoded back into an image. At inference time, this process is repeated autoregressively: predicted frames become part of the context for predicting future frames. Because prediction happens in latent space and uses consistency models, the simulator can run interactively while remaining stable over long horizons.
How is it different from prior works?
This differs from several existing approaches to robot simulation and world modeling. Classical physics simulators can be powerful, but they often require manually specifying object geometry, contact dynamics, friction, and deformation, and the resulting simulation may still have a large sim-to-real gap. Recent video-generation and world-model methods offer a more data-driven alternative, but many are either not explicitly conditioned on robot actions, too slow for real-time interaction, closed-source, or unstable under long-horizon rollouts.
In contrast, our Interactive World Simulator is action-conditioned, produces physically accurate pixel-level predictions, and supports stable interactions for more than 10 minutes at 15 FPS on a single consumer RTX 4090 GPU. This makes it practical not only as a visual prediction model, but as an interactive engine for collecting policy-training data and evaluating robot policies reproducibly. It has multiple applications.
Application 1: scalable data generation
If our simulator is good enough, can demonstrations collected using this world model actually replace real demonstrations for training imitation learning policies?
To answer this, we collected demonstrations entirely inside our world simulator and then trained imitation learning policies on 0% real-world data and 100% generated data. We deployed the trained policies directly on the real robot. The deployed policies do not just complete the tasks. They remain robust under continuous human perturbations. This demonstrates that the generated data quality is comparable to real data.
Application 2: faithful policy evaluation
Evaluating a robot policy in the real world is hard: you need to reset the scene, rerun the policy many times, and compare across checkpoints under matched conditions. In practice, this is not scalable and reproducible.
In contrast, we could roll out policies in our world model for reproducible evaluation. We evaluated the same four policies (DP, ACT, π0, π0.5) inside the simulator and on the real robot, with the same initial configurations. Each point in our evaluation is a policy checkpoint, scored in both real world and world model. We observe a strong correlation between the two scores, across tasks and across policies. Qualitatively, good policies that succeed in the simulator also succeed on the real robot, and bad policies that fail in the simulator also fail on the real robot.
Looking forward
Action-conditioned video prediction has long shown great potential for robotics, but existing approaches have been either too slow for interactive use or too brittle under long-horizon inference. By addressing both of these — stability and computational efficiency — the Interactive World Simulator becomes a practical engine for two things at once: training imitation policies on simulator-generated data that perform comparably to those trained on real-world demonstrations, and evaluating policies in a way that closely tracks real-world performance.
Going forward, we will extend the framework to more diverse environments and increasingly complex manipulation tasks, to further unlock the potential of large-scale robotic data. An important direction for future work is to study how the performance of world models scales with increasing amounts of interaction data and computational resources. Understanding these scaling behaviors could guide the design of larger and more capable world models for robotics.
AUAI is supported by:









